From your question to a trusted answer.
One request, followed end to end. This page explains what happens between a team member typing a question and the answer they can rely on.
Six things happen to every question. None of them require you to do anything.
Protected at the edge
Attacks, bots, and floods are stopped before they reach your data. Every connection is encrypted before it enters.
Encrypted entry
Traffic stays encrypted from your browser to the last service. New capabilities roll out without downtime.
Private workspace
One place for your team to work with AI. Accounts, roles, and an admin console that decides who sees what.
Your documents, understood
Files are processed privately and made searchable by meaning, not just keywords. Answers cite their sources.
Full visibility
Every answer is traceable. Every dollar of AI spend is accounted for. Prompts improve without a release.
Your choice of models
The best model for each job, swapped when a better or cheaper one appears. Never locked in.
One place for your team to work with AI.
A chat interface your team already knows how to use. Shared history, roles, and an admin console for who can access which documents.
- Team accounts and roles
- Shared and private conversations
- Admin controls for documents and access
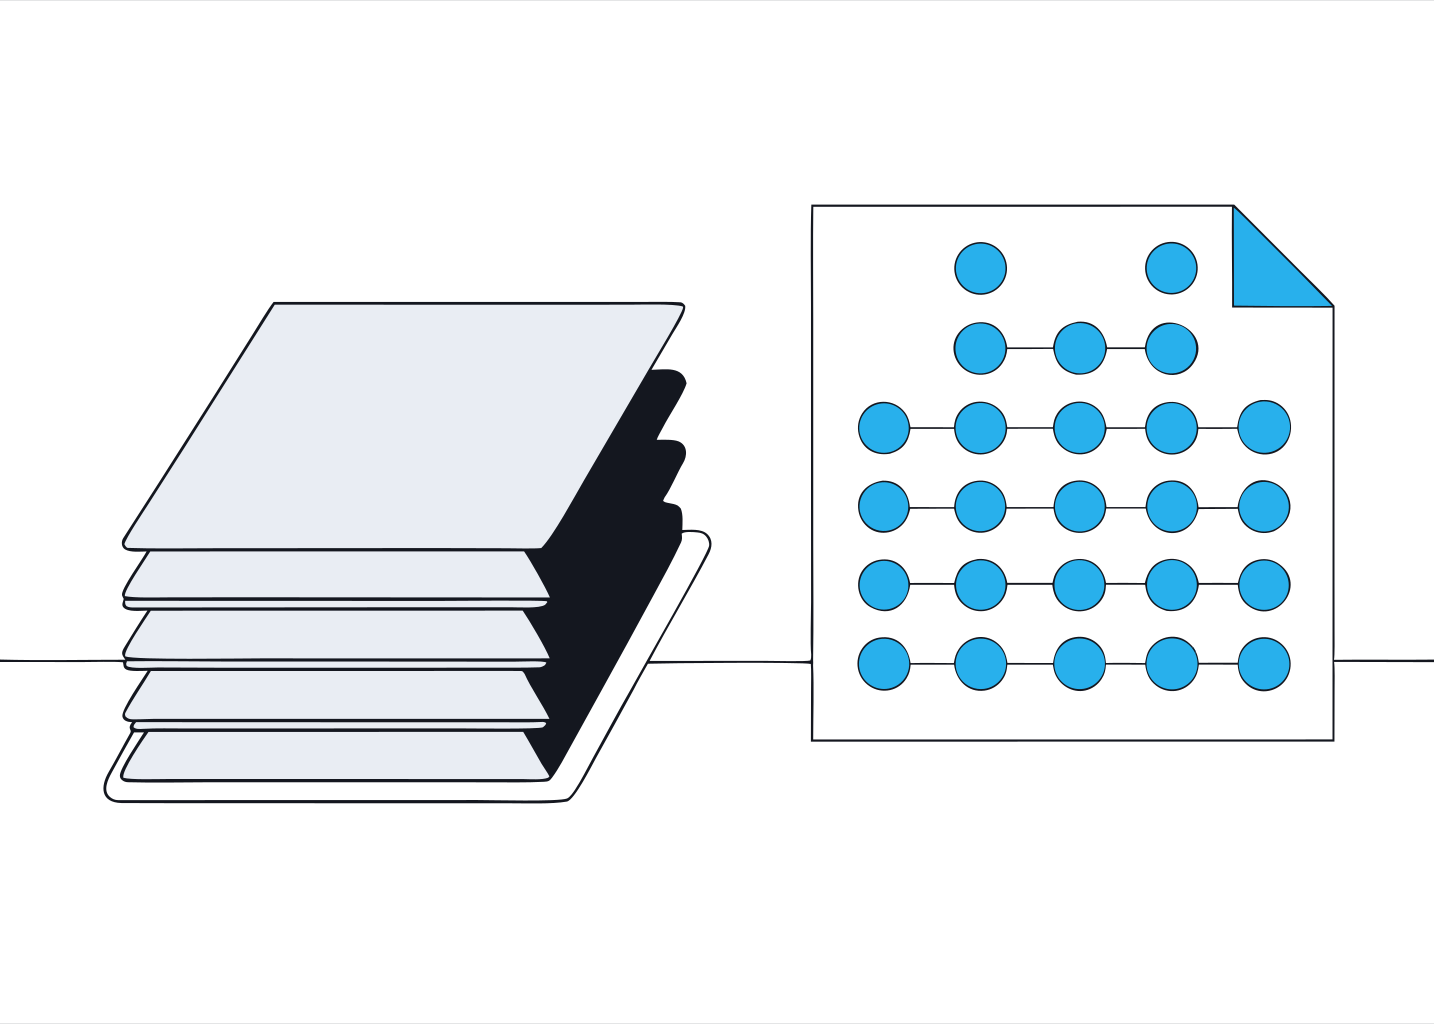
Answers grounded in your own material, with the source shown.
Upload files or connect the places they live. They are broken down, indexed by meaning, and kept on your infrastructure. Every answer shows where it came from.
- Contracts, procedures, tickets, spreadsheets
- Answers with sources, always
- Nothing leaves your environment
See what your team did, what the model did, and what it cost.
Two views on the same system. One shows what your team does. The other shows what the model did, what it cost, and how well it performed.
- Usage by team and by person
- Cost per conversation and per model
- Quality tracking and prompt improvement without a release
Every layer runs on its own dedicated server.
Growth in one place never slows another. Adding capacity means adding to one layer, not rebuilding the platform.
Search
Finds the right passage in millions of pages in milliseconds.
Records
Accounts, conversations, and settings, kept safe and consistent.
Memory
Hot data in memory so nothing waits on the disk.
Background work
Large uploads and scheduled jobs run off to the side. A conversation never waits.
Analytics
Months of usage answered in a blink, without slowing the product.
Files and backups
Uploads and backups with a home of their own, versioned and offsite.
Use the best model for each job. Switch when a better one appears.
Your data and your workflow stay on your platform. The model is a supplier: eighteen providers today, from the frontier labs to open-weight models you can run on your own hardware. Visibility shows whether a switch was worth it.
 OpenAI
 Anthropic
 Google Gemini
 Azure OpenAI
 Meta Llama
 Mistral
 Amazon Bedrock
 Cohere
 xAI Grok
 DeepSeek
 Moonshot Kimi
 Alibaba Qwen
 Z.ai GLM
 MiniMax
 Perplexity
 NVIDIA
 Hugging Face
 Ollama